Engineer First LLM Cache Strategies: Routing Aware Prefixes, SphereLFU, MLflow
Use a layered caching approach: exact-match request caching, prefix/KV caching, and selective semantic caching, stacked in that order of precedence. Turn on exact-match and prefix caching at your gateway first, since both are low-risk and near-universal wins. Only enable semantic caching after you've collected real traffic and run offline replay tests. In the meantime, coalesce in-flight identical requests and instrument hit/miss metrics before you touch anything else.
TL;DR:
- Exact-match caching offers the highest hit rate for repetitive queries, especially in FAQ systems, with minimal latency and no accuracy risk.
- Prefix caching depends on strict prompt structuring and consistent routing, as even minor formatting differences break byte-for-byte matches, reducing effectiveness.
- Semantic caching provides significant savings on paraphrased queries but introduces higher complexity and accuracy risk, requiring careful threshold tuning and verification.
- Proper cache management involves measuring hit and miss rates per layer, implementing request coalescing, and controlling cache invalidation through versioning and TTLs.
- Using tools like MLflow for tracing cache operations and evaluating false-positive rates helps ensure caching systems deliver correct answers without silent errors.
Table of Contents
- What Are the Three Layers of LLM Cache Strategies?
- Building Exact-Match Request Caching at the Gateway
- How Do You Get Prefix Caching to Actually Hit?
- When Is Semantic Caching Worth the Accuracy Risk?
- Choosing the Right Cache Stack for Your Workload
- Building an Operational Checklist for LLM Cache Management
- Tracing and Evaluating Cache Correctness With MLflow
- Which LLM Platforms Support These Cache Strategies?
- Scaling Cache Infrastructure Across Distributed LLM Serving
- Guarding Data Privacy When You Cache LLM Responses
- Getting Cache Rollout Right the First Time
- Validate Your Cache Strategy With MLflow's Tracing Tools
- Sources
- FAQ
What Are the Three Layers of LLM Cache Strategies?
Every serious LLM cache strategy resolves to the same three-layer model, and knowing which layer handles which job is the difference between a cache that saves money and one that quietly serves wrong answers.
Prefix (KV) caching lives at the inference engine level. It reuses the attention key-value states computed for a prompt's shared prefix, so the model doesn't recompute tokens it has already processed. Exact-match request caching sits one layer up, usually at the gateway or application layer. It hashes the full request (model, prompt, parameters) and returns a stored response byte-for-byte when the hash matches. Semantic caching sits highest in the stack. It embeds the incoming query, searches a vector store for a similar past query, and returns a cached response when similarity clears a threshold, typically somewhere between 0.80 and 0.95 depending on risk tolerance.
The recommended lookup order runs from cheapest and safest to most expensive and riskiest:
- Check exact-match cache first. It's a hash lookup, costs almost nothing, and carries zero accuracy risk.
- Fall through to prefix/KV caching for anything that reaches the model, since it's handled automatically by the inference engine when prompts share a structure.
- Only fall through to semantic cache lookup for endpoints where near-duplicate queries are common and wrong answers are tolerable.
Rough trade-offs: exact-match caching adds negligible latency and carries essentially no accuracy risk, but its hit rate depends entirely on how much traffic repeats verbatim. Prefix caching cuts time-to-first-token substantially on long system prompts with no accuracy risk at all, since it's byte-identical reuse, but it requires careful prompt structuring. Semantic caching offers the largest potential hit-rate lift on paraphrased traffic, at the cost of real implementation complexity and a nonzero risk of serving a subtly wrong answer.
Building Exact-Match Request Caching at the Gateway
Exact-match caching for LLM responses is the easiest layer to ship and often the first place teams see a real dent in the inference bill. It works exactly like an HTTP cache: hash the request, store the response, serve it again when the same hash shows up.
The hash key needs more than just the raw prompt text. Build it from the model identifier, a hash of the prompt template (not just the filled-in values), sampling parameters like temperature and top_p, and, critically, a version tag for any retrieval artifacts the prompt depends on. If your RAG pipeline pulls from a document corpus, tie the cache key to that corpus's version number; otherwise, you'll keep serving answers built from a document set that no longer exists.
Here's a practical build sequence:
- Normalize the request (strip whitespace, sort JSON keys) before hashing to avoid cache misses caused by formatting noise.
- Compute a single hash from model ID + template hash + parameters + corpus version.
- Check an in-memory or Redis-backed store for that hash before calling the model.
- On a miss, invoke the model, store the response with a TTL, and return it.
- Wrap the whole lookup-then-invoke sequence in request coalescing so two identical requests arriving milliseconds apart don't both trigger a model call.
TTLs should match how fast your underlying data changes. A support FAQ bot pulling from a static knowledge base can cache for hours or days. A RAG system over a frequently updated document set needs content-triggered invalidation, where a corpus update bumps the version tag and implicitly invalidates every cache entry tied to the old version.
Hit rates vary sharply by endpoint type. FAQ-style endpoints with a narrow set of common questions often see high exact-match hit rates because users tend to phrase the same question the same way repeatedly. Open-ended chat endpoints see far lower exact-match hit rates, since conversational phrasing rarely repeats verbatim, which is exactly why prefix and semantic caching exist as complementary layers rather than substitutes.
Pro Tip: Request coalescing (also called in-flight deduplication) catches a failure mode exact-match caching alone misses: a traffic spike where 50 identical requests land before the first one finishes. Without coalescing, you pay for 50 model calls instead of one.
How Do You Get Prefix Caching to Actually Hit?
Prefix caching reuses key-value states from the attention mechanism, but only when the prefix is byte-for-byte identical to something already processed. One extra space, a reordered JSON field, or a timestamp injected into your system prompt breaks the match and silently forces full recomputation, even though providers market prefix caching as automatic.
That byte-for-byte requirement should shape how you write prompts. Structure every prompt with a stable system block first, containing instructions, tool definitions, and anything that doesn't change between requests, followed by a variable user block. Never interleave the two. Never inject a timestamp, a random request ID, or a session-specific value into the stable block. If you need that metadata, pass it through a separate parameter, not the prompt text.
Routing matters just as much as prompt structure, and it's the piece teams overlook most often:
- Round-robin load balancing across stateless inference pods defeats prefix caching, because a request that would hit the cache on pod A gets routed to pod B, which has never seen that prefix.
- Sticky sessions or consistent hashing, keyed on a stable identifier like user ID or conversation ID, keep related requests landing on the same pod so the KV cache actually gets reused.
- A shared cache backend across pods is the alternative when session stickiness isn't practical, though it adds infrastructure to maintain.
Detecting prefix misses caused by formatting drift takes deliberate instrumentation, since the model still returns a correct answer. It just costs more and takes longer. Trace every request with the exact prompt sent to the engine, and diff prefixes across requests that should have matched. A tracing layer that captures the literal bytes going into the model call, not just a summary, is the only reliable way to catch this class of bug before it burns through your inference budget.
Pro Tip: If your prefix hit rate looks lower than expected, check for hidden non-determinism first, things like dictionary key ordering in a templating engine or a library that appends a random nonce. That's a far more common culprit than routing.
When Is Semantic Caching Worth the Accuracy Risk?
Semantic caching for LLM responses is the highest-leverage layer for paraphrase-heavy traffic and the layer most likely to bite you if you skip the guardrails. The end-to-end flow looks like this: embed the incoming query, run a vector search against previously cached queries, check whether the top match clears a similarity threshold, optionally run a token-level verification pass, then return the cached response instead of calling the model.
Start conservative. A similarity threshold in the 0.90 to 0.95 range is a reasonable floor for a first production rollout, since it only matches queries that are nearly identical in meaning. Once you've measured false-positive rates on real traffic, you can tune down toward 0.80 to 0.90 to widen coverage. Going lower without measurement is how teams end up serving confidently wrong answers to genuinely different questions.
Vector search itself adds only about 5 to 20 milliseconds of overhead, compared to LLM calls that routinely take one to five seconds. On cache-friendly, high-repeat workloads, benchmarks from AWS show latency reductions up to roughly 88% and cost reductions up to roughly 86%, though those figures represent ideal-case scenarios rather than typical production averages.
Vector store choice shapes your latency and operational profile more than most teams expect:
- pgvector works well if you already run Postgres and want one fewer moving part, at the cost of scaling further than a purpose-built vector database.
- Managed vector databases (dedicated services) handle scale and indexing automatically but add another network hop and another vendor to operate.
- RedisVector trades some indexing sophistication for very low latency, which matters when the whole point of the cache is shaving milliseconds off a hot path.
The single most important detail for chat-based systems: your embedding must include the conversational context window, not just the latest message in isolation. Microsoft's guidance on semantic caching is explicit that omitting chat history produces incorrect replays, because "What's the return policy?" means something completely different depending on what the last three messages were about.
Guardrails that separate a safe rollout from an incident:
- Run offline replay tests against a sample of real traffic before enabling semantic cache in production, measuring hit rate and false-positive rate side by side.
- Restrict early semantic caching to low-stakes, FAQ-like traffic rather than agentic or transactional flows, where a wrong cached answer causes real damage rather than mild annoyance.
- Add a token-level verification step, comparing the first N tokens of a fresh generation against the cached response or running a lightweight classifier, to catch poisoned or context-mismatched entries before they reach a user.
- Flag low-confidence matches (just above threshold) for human review during the first weeks of rollout instead of auto-serving them.
Choosing the Right Cache Stack for Your Workload
The right combination of layers depends on three variables: how much your traffic repeats, how much of that repetition is verbatim versus paraphrased, and how much damage a stale or wrong answer would do.
High query volume with low paraphrase variance, like an internal support FAQ bot, is the easiest case. Exact-match caching alone often captures most of the available savings, since users tend to type the same handful of questions.
A read-mostly RAG system over a document corpus benefits from all three layers stacked together: exact-match for repeated literal queries, prefix caching for the stable retrieval-and-instruction scaffolding that surrounds every query, and semantic caching tuned conservatively for the paraphrase traffic that exact-match misses.
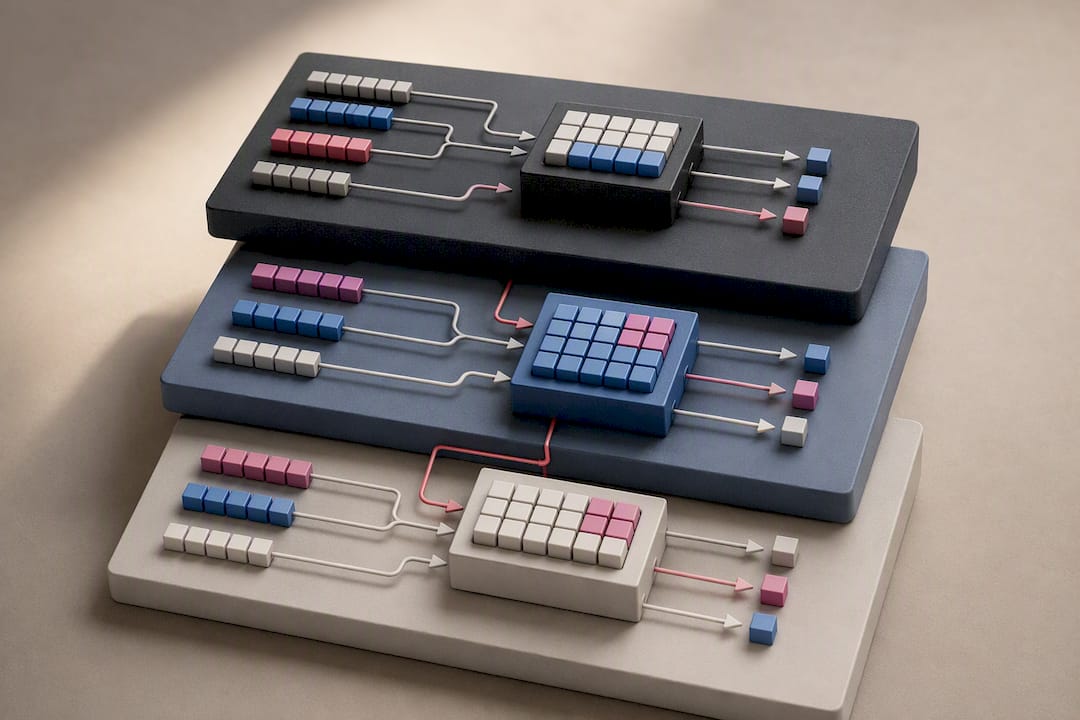
Agentic, multi-step workflows are the case for restraint. Each step's output feeds the next step's input, so a wrong cached response early in the chain compounds. Lean on exact-match and prefix caching here, and think twice before layering semantic caching onto anything that isn't a clearly bounded, low-stakes sub-task.
In prose terms, the trade-off runs like this: exact-match caching carries minimal accuracy risk, minimal latency overhead, and minimal engineering cost, making it close to a default. Prefix caching carries no accuracy risk and meaningful latency benefit, but real engineering cost in routing and prompt discipline. Semantic caching carries the highest accuracy risk, the biggest potential latency and cost win, and the highest engineering cost, which is exactly why it belongs last in the rollout sequence, not first.
Building an Operational Checklist for LLM Cache Management
Knowing how to manage LLM cache behavior in production comes down to four disciplines: what you measure, how you evict, how you secure, and how you test before shipping changes.
Metrics worth a dashboard, at minimum:
- Hit rate and miss rate, broken out per cache layer, not blended into one number.
- False-positive rate for semantic caching, tracked from replay tests and ongoing sampled review.
- Cost delta, comparing actual model-call spend against a no-cache baseline for the same traffic.
- Median (and p95) latency, separated for cache hits versus cache misses, so a latency regression in one path doesn't hide inside an average.
Eviction policy matters more for semantic caches than most teams assume. Research on semantic cache eviction shows that finding the mathematically optimal eviction policy is NP-hard, but frequency-biased online policies, particularly SphereLFU, a variant of least-frequently-used eviction adapted for vector similarity clusters, consistently outperform plain least-recently-used (LRU) eviction across varied workloads. LRU assumes recency predicts future value; semantic query traffic is often better predicted by how often a topic cluster recurs, which is exactly what LFU-style policies capture.
Security deserves the same attention as accuracy. A poisoned or manipulated cache entry can serve the same wrong answer to every future matching query until someone notices. Token-level verification on cached completions, comparing generated output against what a fresh call would produce, catches this before it becomes a pattern rather than a one-off.
Pro Tip: Treat cache warming as part of your rollout, not an afterthought. Preloading known high-traffic queries before a launch avoids a cold-cache spike in latency and cost on day one.
Testing discipline closes the loop: offline replay against captured traffic first, then A/B gating on a small percentage of live traffic, then a full rollout once false-positive rates and cost savings both look stable.
Tracing and Evaluating Cache Correctness With MLflow
Knowing your cache hit rate is different from knowing your cache is right. MLflow's tracing capabilities let you instrument every stage of a cache lookup, capturing the request that entered the pipeline, the embedding computed, the vector search result and similarity score, and the final response returned, whether it came from cache or a fresh model call.
Practical instrumentation points worth wrapping in spans:
- Before and after the exact-match hash lookup, so you can see hit/miss decisions in the trace itself.
- Around the embedding call for semantic caching, to catch latency regressions in that step separately from the vector query.
- At the vector database query, capturing the similarity score returned, not just a pass/fail on the threshold.
- At the final model invocation, so a cache miss and its resulting generation sit in the same trace as the lookup that preceded it.
Layering LLM-as-a-Judge evaluation on top of cached responses gives you a way to periodically score whether cached answers still hold up against fresh generations for the same query cluster, catching semantic drift before it shows up as a support ticket.
Which LLM Platforms Support These Cache Strategies?
Most major model providers now expose some form of prompt or prefix caching directly through their API, which means your integration work is less about building the KV cache mechanism yourself and more about structuring requests to trigger it reliably. That's a documentation-reading exercise as much as an engineering one: each provider has slightly different rules for what counts as a cacheable prefix and how long cached segments persist.
For the exact-match and semantic layers, integration usually happens at a layer you control, an API gateway, a request-handling middleware, or a dedicated caching service sitting between your application and whichever model endpoint you call. This is deliberate: keeping exact-match and semantic caching provider-agnostic means you can swap or mix model providers without rebuilding your caching logic each time.
If you're running open-source models on self-hosted inference engines, prefix caching typically ships as a built-in engine feature you enable through configuration rather than something you implement from scratch. The engineering work shifts toward the routing problem described earlier, ensuring requests that should hit the same KV cache actually land on the same instance.
Frameworks that orchestrate multi-step or agentic workflows add another wrinkle: each step in a chain may call a different model or a different prompt template, which means your cache key logic needs to account for which step generated a request, not just the request content itself. Treat each distinct step type as its own cache namespace rather than sharing one flat key space across an entire agent's execution.
Scaling Cache Infrastructure Across Distributed LLM Serving
Caching that works cleanly on a single instance tends to break in predictable ways once you scale to multiple pods, regions, or model providers. The routing problem discussed for prefix caching, where round-robin load balancing defeats KV reuse, is the most common failure, but it's not the only one.
Shared state becomes a bottleneck if you're not careful. A single Redis instance backing your exact-match and semantic caches works fine at moderate scale, but as request volume grows, that instance can become a shared point of contention across every serving pod. Sharding the cache by a stable key, such as a hash of the model ID or tenant ID, spreads that load without breaking the coalescing and deduplication logic that depends on requests reliably finding the same cache entry.
Cross-region deployments raise a harder question: does a cache entry generated in one region apply in another? For exact-match and semantic caching, the answer is usually yes, since the underlying model and prompt logic don't change by geography, and replicating a shared cache across regions can meaningfully raise hit rates for global traffic. Prefix/KV caching is different. It's tied to the specific inference engine instance holding the attention state in memory, so it doesn't replicate across regions the same way, and each regional cluster effectively builds its own KV cache independently.
Capacity planning should account for cache memory as its own resource line, separate from model-serving compute. A semantic cache holding embeddings for millions of distinct queries has real memory and storage costs that scale with your knowledge base's diversity, not just your traffic volume.
Guarding Data Privacy When You Cache LLM Responses
Cached responses often contain the same sensitive content as the original request, which means caching multiplies your data retention footprint rather than shrinking it. If a user's prompt included personal information, that information now lives in two places: the model provider's logs (subject to their retention policy) and your own cache store (subject to yours).
TTLs aren't just a freshness mechanism here. They're a privacy control. Set them deliberately for any cache holding user-specific or regulated content, and don't extend TTLs on sensitive-content caches just because the hit rate looks good. Consider excluding requests flagged as containing personal data from caching entirely, particularly in the semantic layer, where a vector embedding of sensitive content sits in a searchable index that a cache-poisoning or unauthorized-access attempt could exploit.
Multi-tenant systems need namespace isolation enforced at the cache-key level, not just at the application layer. A cache key that doesn't include a tenant identifier can leak one customer's cached response to another customer's semantically similar query, which is a considerably worse failure mode than a stale answer.
Getting Cache Rollout Right the First Time
Sequence rollout deliberately: baseline your metrics before touching anything, ship exact-match and prefix caching first, run offline replay tests against real traffic, then gate semantic caching behind a small percentage of live requests before going wide.
The mistakes I see most often are all sequencing mistakes. Teams enable semantic caching globally before running a single replay test, because it's the layer with the flashiest cost-savings numbers. Teams ship prefix caching without touching their load balancer, then wonder why hit rates look flat. Teams monitor cost savings closely and forget to monitor false-positive rates at all.
None of this is purely an engineering decision. Getting it right means SRE, ML engineers, and product owners agreeing upfront on what an acceptable false-positive rate looks like for each endpoint, before the first line of caching code ships.
— Kevin
Validate Your Cache Strategy With MLflow's Tracing Tools
The layered approach in this article only works if you can actually see what your cache is doing, and that's precisely where most homegrown caching setups fall short: teams ship the cache, watch the bill drop, and have no systematic way to catch the day a semantic match quietly serves the wrong answer. This visibility can be provided without needing to bolt together a separate observability stack.
A few ways teams use it specifically for cache validation:
- LLM tracing captures every step of a cache lookup, embedding call, vector search, and model invocation in one connected trace, so a false-positive semantic match is traceable back to the exact query that triggered it.
- AI Gateway centralizes prompt versioning and routing across providers, which matters directly for exact-match cache keys tied to prompt template versions.
- LLM-as-a-Judge evaluation scores cached responses against fresh generations on a recurring basis, catching semantic drift before it becomes a pattern of complaints.
If you're building out an inference caching layer and need a way to prove it's saving money without silently degrading answer quality, explore Mlflow's GenAI platform and see how tracing and evaluation fit into your existing serving stack.
Sources
- The Complete Guide to Inference Caching in LLMs
- Optimize LLM response costs and latency with effective caching (AWS)
- Semantic caching heuristics and online policies (arXiv)
- Implement a semantic cache with Azure Cosmos DB (Microsoft docs)
- What is semantic caching? (Redis blog)
FAQ
What Is L1, L2, L3, and L4 Cache in the Context of LLMs?
L1 through L4 normally describe CPU hardware cache tiers, not LLM caching, but engineers often map the idea onto LLM systems as: exact-match cache (fastest, most restrictive), prefix/KV cache (engine-level), semantic cache (broadest match, application-level), and a model-provider-side cache (outside your direct control).
What Are LLM Cache Hits?
A cache hit occurs when an incoming request matches a stored entry closely enough to reuse it instead of calling the model again, whether that match is an exact hash match, a shared prompt prefix, or a semantic similarity above your chosen threshold.
What Is the 80/20 Rule in Caching and How Does It Work?
Applied to LLM traffic, it means a small share of distinct queries or query patterns typically accounts for most of the request volume, which is why exact-match and prefix caching alone often capture a large portion of available savings before you add semantic caching at all.
What Is the Best Caching Strategy for LLMs?
There's no single best layer. The most reliable approach layers exact-match caching and prefix/KV caching first, since both carry minimal accuracy risk, then adds semantic caching selectively for paraphrase-heavy, low-stakes traffic after offline replay testing confirms an acceptable false-positive rate.
How Do I Know if My Semantic Cache Is Making Mistakes?
Track false-positive rate directly through offline replay tests against sampled real traffic, and add token-level verification on cached responses so a mismatch gets caught before it reaches a user rather than after.