Two Tables, One Rollout: Prompt Registry Design for Engineers
A prompt registry is a system-of-record for versioned prompt templates and their release state. The best production design pairs an immutable, content-hash version store with small mutable pointer rows for environment aliases, logs the resolved version on every request, and always keeps a compiled or cached fallback so inference never stalls when the registry itself is unhealthy.
TL;DR:
- Versioned prompt templates should include variables, JSON schema, model parameters, and metadata to prevent drift and ensure consistent rollbacks.
- A prompt registry must have immutable version storage, environment-specific pointers, and layered fallback mechanisms to support reliability during outages.
- Traffic can be safely rolled out using incremental basis point control and must always keep a 'previous' pointer for quick recovery from failures.
- Managing access through role-based permissions and approval workflows is essential to prevent accidental or unauthorized production changes.
- MLflow offers a practical, open-source platform for prompt versioning, tracking, and governance, suitable for teams transitioning from code-based prompt management.
Table of Contents
- What Does a Production Prompt Registry Need to Do?
- Which Architecture Pattern Fits Your Team?
- What Fields Belong in a Prompt Template Schema?
- How Should You Handle Versioning and Releases?
- How Do You Resolve Prompts at Inference Time?
- What Should You Log and Measure?
- How Do You Govern Access Without Slowing Teams Down?
- MLflow's Take on Prompt Registry Design
- Try MLflow for Your Prompt Registry
- Sources
- FAQ
What Does a Production Prompt Registry Need to Do?
A registry that only stores text is a glorified file share. Production systems need six capabilities working together, and skipping any one of them tends to surface as an incident later rather than a gap in a design review.
Template storage has to hold variables and a JSON Schema alongside the raw text, so a missing field fails fast instead of silently rendering a broken prompt. Model parameters, like temperature and token limits, belong on the version row itself rather than in application code, because storing runtime params with the version is what makes a rollback actually restore prior behavior instead of just prior wording.
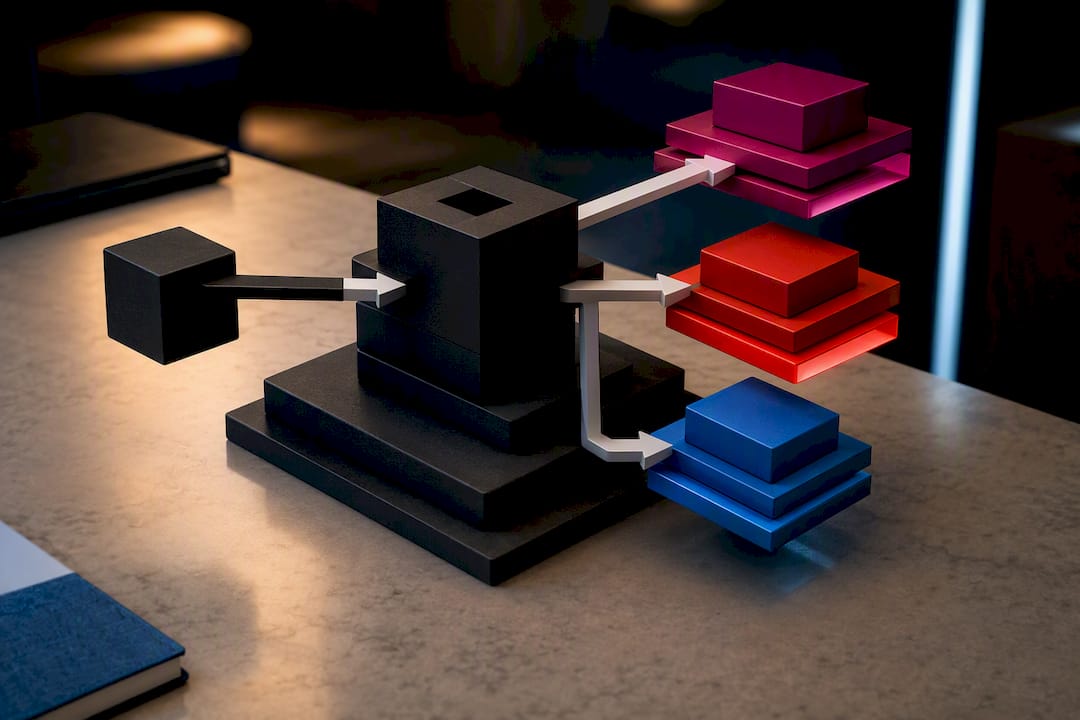
The core data shape is two tables: an immutable version store and a pointer table that maps environment aliases (staging, prod) to a specific version, with pointer updates acting as the release mechanism itself.
Beyond that foundation, a mature registry adds:
- Search, tags, and metadata so teams can find and reuse prompts instead of rewriting them
- Approval workflows and staged releases, including per-tenant rollout controlled in basis points
- Design-time APIs/SDKs for editing plus a separate, fast runtime resolution path
- Audit telemetry that captures which version served which request, every time
Treat any one of these as optional and you are building a registry that works in the demo and breaks under real traffic.
Which Architecture Pattern Fits Your Team?
The right topology depends less on ambition and more on team shape. A file-in-git approach, compiled into the binary at build time, works well for small teams where engineers author every prompt. A registry earns its added complexity specifically when non-engineers start editing prompts and when rollbacks need to be instant and auditable rather than a redeploy.
That decision cascades into a consistency question. Distributed systems force a choice between consistency (CP) and availability (AP), and prompt registries are no exception. For most high-traffic inference paths, availability wins, since a stale prompt is far less damaging than a failed request. But some registries genuinely need CP guarantees, particularly where two conflicting "prod" pointers could cause compliance or safety ambiguity.
A few principles hold regardless of which side you land on:
- Content-hash versions guarantee immutability: identical text can never produce two different version IDs, which makes request-time logging verifiable after the fact.
- Pointer rows should be small, mutable, and cheap to update, since they are the actual release lever.
- Runtime resilience should be layered: compiled defaults shipped with the build, a cached copy of the last known-good compiled version, and the live registry as the freshest but least reliable tier.
- Start minimal. Overbuilding for hypothetical scale before you have multi-team editing or compliance pressure just adds operational burden nobody asked for.
Pro Tip: Build the three-tier fallback before you build the admin UI. Teams that reverse this order end up with a beautiful editing experience sitting on top of a registry that takes down inference the first time its database has a bad afternoon.
What Fields Belong in a Prompt Template Schema?
A prompt_version row needs a fixed set of fields, and treating any of them as optional is how drift creeps in months later. At minimum, plan for:
prompt_id— the stable identifier for the logical prompt, unchanged across versions.version— a content hash of the rendered template, guaranteeing that edits always create a new, immutable record.template— the raw text, including support for chat-style multi-message structures (system, user, assistant turns) and few-shot exemplars where relevant.variables— a JSON Schema describing every placeholder, its type, and whether it's required.params— model hints like temperature and token ceilings, stored with the version rather than in calling code.model_hint,notes,author,created_at— metadata for discovery and forensic review.
Prompt components like instructions, few-shot examples, and role cues render differently across model providers, which is exactly why the schema needs to be explicit rather than assumed. Before publish, dry-render every candidate version against a set of sample inputs. That single check catches missing variables and incompatible parameter combinations before they reach a live request, and it costs almost nothing to run in a CI pipeline.
How Should You Handle Versioning and Releases?
Treat every prompt edit as a new artifact, never an in-place mutation. The workflow below scales from a two-person team to an organization running dozens of prompts across multiple products.
- Author. Draft or edit the template. Saving generates a new content-hash version automatically; there is no "edit version 3" action, only "create version 4."
- Evaluate offline. Run the candidate against an automated eval suite before it touches production traffic. LLM-as-a-judge comparisons work well here, paired with a fixed sample size large enough to detect a meaningful quality delta, not just noise.
- Promote to staging. Point the
stagingalias at the new version. Nothing in production changes yet. - Canary in production. Update the
prodpointer'srollout_bpsfield to send a small slice of traffic, often starting around 0.5% for high-traffic features, to the new version while the rest keeps serving the prior one. - Ramp or roll back. If canary metrics hold, increase
rollout_bpstoward 10000 (100%) in stages. If they don't, flip the pointer'spreviousfield back to the last known-good version.
The pointer update is the release action, full stop. This two-table pattern, immutable versions plus mutable pointers, means rollback is a single write, not a redeploy, and it means every request row can log exactly which version served it.
Pro Tip: Keep the previous pointer field populated at all times, not just during an active rollout. The moment you need it is the moment you don't have time to go digging through a changelog.
How Do You Resolve Prompts at Inference Time?
Resolution has to be fast and it has to survive the registry going down. A three-tier approach handles both: compiled defaults baked into the build as a last resort, a cached copy of the most recently resolved compiled version for normal operation, and a live call to the registry for freshness when latency budgets allow it.
For any experiment or gradual rollout, assignment needs to be deterministic rather than random per request. A tenant-seeded hash, combining a tenant or user ID with the prompt ID and taking the result modulo 10000, gives you sticky bucket assignment that lines up cleanly with rollout_bps and keeps a single user from flipping between prompt versions mid-session.
Beyond the resolution path itself, four operational rules keep this layer safe:
- Define an explicit fallback policy for unknown or missing versions. Silent failure is worse than a logged default.
- Log every fallback event. If your compiled default is serving 8% of traffic, you want to know before a customer tells you.
- Validate user-supplied variables against the schema before rendering, catching malformed input early.
- Never render raw user input directly into a prompt without checking for accidental PII leakage into logs or downstream calls.
What Should You Log and Measure?
Every inference request should write a row that captures prompt_id, version, model, provider, params, cost, and latency at minimum. Without that row, "which prompt caused this regression" becomes archaeology instead of a query.
Quality signals need to be attributable back to a specific version, not just averaged across "the prompt" in general. That means tracking conversion or task-success metrics, hallucination proxies, and correctness scores per version, then comparing them across the pointer history.
For gating releases, offline evaluation pipelines matter more than most teams initially budget for. A growing taxonomy of prompting techniques exists specifically because prompt behavior is hard to verify by eye, and LLM-as-a-judge scoring gives you a repeatable, automatable gate instead of a human skimming ten outputs before shipping.
A few practical habits make the eval gate trustworthy:
- Fix your canary sample size in advance so you're not eyeballing statistical noise as a signal.
- Run the same eval suite against every candidate version, not a custom check per release.
- Treat a canary that underperforms the eval suite's prediction as a signal to investigate the eval suite, not just the prompt.
- Store eval scores alongside the version row so quality history survives beyond the current sprint.
Statistic Callout: Rollout controls expressed in basis points give you granular control down to a 0.5% first-stage rollout, fine enough to catch a regression before it touches more than a sliver of production traffic.
How Do You Govern Access Without Slowing Teams Down?
Scaling prompt editing beyond a single engineering team requires real role boundaries, not a shared spreadsheet with a polite request to "ask before changing prod."
A workable model uses three roles, viewer, editor, and admin, scoped per team or project so a marketing team's editors can't touch a fraud-detection prompt by accident. Protected aliases matter just as much: any pointer change targeting prod should require an approval step, while staging can stay open for faster iteration.
- Keep version rows and pointer updates immutable and timestamped with
updated_byandupdated_atfor forensic queries. - Require a second approver for any prod pointer change on a high-traffic or safety-sensitive prompt.
- Store secrets and API keys separately from prompt text; never let a template field double as a credential store.
- Build a migration checklist for extracting prompts currently hardcoded in application code, since that inline debt is usually where governance gaps start.
MLflow's Take on Prompt Registry Design
These patterns, immutable versions, pointer-based releases, and layered runtime fallbacks, aren't theoretical for us. MLflow is built as an open-source platform for managing the GenAI and LLM application lifecycle, with orchestration and deployment of AI agents as a core focus.
That includes production-grade observability through deep tracing of agentic reasoning, automated evaluation with LLM-as-a-Judge, and a centralized AI Gateway for prompt management and cross-provider governance. The design principles in this guide are the same ones we've built into that platform.
— Kevin
Try MLflow for Your Prompt Registry
If you're still managing prompts in application code or a shared document, the fastest path forward isn't a full migration. It's a small pilot: pull five or six high-impact prompts into a registry, run them through an offline eval suite, and switch your first release to pointer-based rollouts instead of a deploy.
MLflow's AI Gateway handles secure prompt management and cross-provider governance out of the box, and its GenAI and agent engineering tools give you versioning, tracing, and LLM-as-a-judge evaluation without stitching together three separate systems. For teams comparing prompt component patterns before they migrate, resources like this guide to writing better AI prompts are a useful starting point too. Clone the open-source repository, walk through the getting-started docs, and run your first canary rollout this week.
Sources
- Prompt Registries and Deploying a Prompt Change (Multigrid)
- Prompt engineering concepts (Microsoft Docs)
- dgen_registry design (FoundationDB-beam)
- A taxonomy and survey of prompting techniques (arXiv)
FAQ
What Is a Prompt Registry?
A prompt registry is a system-of-record that stores versioned prompt templates, their variables, model parameters, and release state, separate from application code, so teams can update prompts without a redeploy.
Should I Use a Database or Just Store Prompts in Git?
Git-based storage compiled into the build works well for small, all-engineer teams; a database-backed registry becomes worth the added complexity once non-engineers edit prompts or you need instant, auditable rollbacks.
How Do I Prevent Variable Drift Between Prompt Versions?
Validate every template against a JSON Schema and dry-render it against sample inputs before publish, which catches missing placeholders and incompatible parameter changes before they reach production.
Does MLflow Support Prompt Versioning and Rollouts?
Yes. MLflow's platform includes prompt management and versioning alongside its AI Gateway and evaluation tools, letting teams track version history and govern releases across providers from one place.